ext intitle:cart: Meaning, Search Uses and Important Security Facts
Understand how this advanced search query works, why search engines interpret it differently, and what it reveals about website indexing and e-commerce technology.

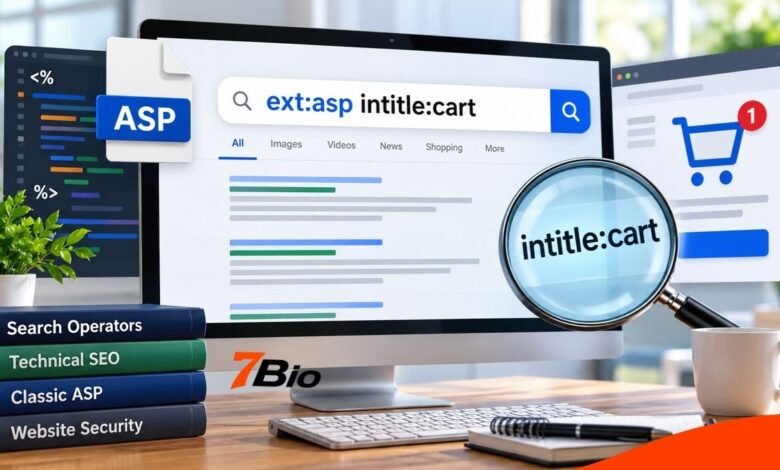
The search expression ext intitle may look like a programming command, but it is actually a combination of advanced search operators. It is designed to narrow search results towards web pages associated with the .asp filename extension and the word “cart” in their titles. The expression is particularly relevant to older e-commerce systems, website indexing, and security research.
An important distinction is often overlooked. Microsoft Bing officially documents the ext: operator, while Google officially documents filetype: for file-type filtering. Consequently, an expression that works as intended in Bing should not automatically be assumed to produce identical results in Google.
Understanding this difference helps website owners, developers, and researchers avoid misleading conclusions about search results.
This article explains the query’s meaning, how its components work, how it relates to Classic ASP shopping carts, and responsible ways to use search operators.
What Does ext intitle Mean?
The expression ext intitle combines two search conditions. The first targets a filename extension, while the second searches for a particular word within a webpage’s title.
Its components can be understood separately:
- ext – A Bing-supported search operator intended to return web pages with the .asp filename extension.
- intitle – A title-focused search condition intended to locate pages containing “cart” in their titles.
When interpreted as intended, the combination narrows the search towards ASP-related pages associated with shopping carts.
However, a match does not prove that a website has an active checkout system or any particular security weakness. The query identifies publicly indexed information, not a website’s internal condition.
Understanding the Two Search Operators
How the ext: Operator Works
A filename extension is a suffix attached to a file or URL, such as .html, .pdf, or .asp. Search engines can use extensions and content-type information to classify resources.
Microsoft documents ext: as an advanced Bing search keyword that restricts results to pages with a specified filename extension.
For example, ext:asp is intended to identify web pages associated with the ASP extension.
This can be useful when researching older websites, examining specific file formats, or reviewing a domain’s publicly indexed resources.
Google takes a different documented approach. Its filetype: operator can narrow results according to the file’s HTTP content type or filename extension.
Therefore, when investigating the meaning of ext intitle, the search engine being used is an essential part of the explanation.
How the intitle: Operator Works
The intitle: operator focuses on words appearing in webpage titles.
For example, intitle: cart is intended to find search results whose titles contain “cart”. Those titles might describe an online shopping basket, an order summary, or a cart-related support page.
Search engines use titles as one of several signals to understand and display webpage content. Nevertheless, a title is only descriptive information.
A page called “Shopping Cart” might contain an active purchasing interface, an archived demonstration or an informational explanation. The title alone can’t tell you which one it is.
Comparison of the Search Expressions
| Search expression | Purpose |
|---|---|
ext:asp | Filter by the ASP filename extension in Bing |
intitle:cart | Focus on pages with “cart” in their titles |
ext:asp intitle:cart | Combine extension and title conditions |
filetype:asp intitle:cart | Use Google’s documented file-type filter alongside a title-focused operator |
site:example.com intitle:cart | Investigate cart-related results from a specified example domain |
These expressions are useful research tools, but their results are not guaranteed to be exhaustive.
What Is Classic ASP and Why Is It Relevant?
ASP stands for Active Server Pages, a server-side web technology developed by Microsoft. It lets a web server generate dynamic content using scripts instead of relying entirely on static HTML documents.
Classic ASP became widely used for web applications, business websites, and online retail systems. It was commonly deployed through Microsoft’s Internet Information Services (IIS).
An ASP application can process requests, communicate with databases, and generate content based on server-received information.
This made the technology suitable for applications involving customer accounts, product catalogs and shopping baskets.
Classic ASP should not be confused with ASP.NET. They belong to different generations of Microsoft’s web development technology and have different architectures.
Microsoft continues to describe Classic ASP as supported on supported versions of IIS, with its support lifecycle tied to the underlying Windows operating system. Therefore, identifying a .asp URL does not establish that the application is unsupported.
Why Shopping Cart Pages Are Associated With ASP
An online shopping cart manages a customer’s intended purchases before an order is submitted.
Depending on the application, it may display products, quantities, prices, delivery options, and other information related to an ongoing shopping session.
Older commerce systems sometimes exposed addresses ending in .asp, making those addresses recognizable during search-engine research.
This historical relationship helps explain why ext intitle appears in discussions about legacy web technology.
Still, modern websites can use clean URLs that reveal little about their underlying software. Conversely, an older-looking URL does not necessarily indicate the technology currently powering a website.
How Bing and Google Interpret the Query Differently
One of the most useful things to understand about ext intitle is that search operators are not universal commands.
Bing’s official documentation lists ext: as a filename-extension filter. It also documents title-focused search keywords.
Google’s Search Central documentation instead specifies filetype: for searching by file type or extension.
A comparable Google expression is:
filetype: asp intitle: cart
This is a more defensible starting point when researching ASP-related results through Google because filetype: is part of Google’s published operator documentation.
However, a syntactically meaningful search expression does not guarantee that every relevant result will appear.
Search engines have indexing limitations, ranking systems, and retrieval rules that affect which pages they display.
Google specifically recommends Search Console’s URL Inspection tool for investigating individual URLs rather than relying exclusively on search-operator results.
Why ext intitle Is Associated With Google Dorking.
The phrase Google dorking refers to using advanced search operators to locate specific types of publicly indexed information.
Security researchers may combine search conditions to identify pages, files, or resources relevant to an authorized website assessment.
The OWASP Web Security Testing Guide recognizes search-engine reconnaissance as an information-gathering technique.
In this context, ext intitle can be understood as a search pattern that targets a specific file extension and an e-commerce-related title.
Importantly, Google dorking itself does not bypass passwords, break authentication, or automatically exploit software.
The search engine is returning information from its index.
Finding a page through a search operator should never be confused with establishing that it contains confidential information or a vulnerability.
Security assessments require appropriate authorisation, technical evidence and careful interpretation.
Practical Uses for Website Owners and SEO Professionals
Reviewing Indexed Shopping Cart Pages
Website administrators can use supported search operators to investigate how their own pages appear in public search results.
For instance, an e-commerce business may want to determine whether outdated cart pages remain discoverable after a website redesign.
The administrator can restrict the search to a domain they control and review any matching results.
A cart page appearing in search is not automatically a security problem. Nevertheless, it may deserve attention if it contains unnecessary session-related URLs or provides a poor search landing experience.
Investigating Older Website Components
Developers maintaining Classic ASP applications may use extension-focused searches as a preliminary discovery method.
This can help reveal older URLs that still appear in public search indexes.
For meaningful technical work, however, compare search findings with the application’s actual route configuration, deployment records, and server-side file inventory.
A search engine cannot provide a complete picture of an application’s components.
Improving Technical SEO Decisions
E-commerce websites need clear distinctions between pages intended for search discovery and pages intended for individual customer activity.
Product pages, relevant category pages, and useful buying guides often have stronger reasons to appear in search results than individual shopping baskets.
A typical cart page is tied to a temporary user journey rather than a general information need.
Website owners should therefore review whether such pages genuinely require indexing, based on their content and purpose.
That decision should come from the site’s actual search strategy, not from assuming every URL containing “cart” must be excluded.
A Responsible Method for Auditing Your Own Website
The following approach keeps the investigation practical without relying on unsupported conclusions.
Step 1: Confirm the website and search engine. Start with a domain you own or have explicit permission to examine. Use search operators documented for the selected search engine.
Step 2: Review matching indexed URLs. Examine the page titles and addresses returned by the search. Record potential matches without assuming that the listed pages are currently functioning.
Step 3: Check the pages through authorized tools. Use Google Search Console for individual URL indexing information and website administration tools to establish the actual purpose of each page.
Step 4: Identify unnecessary exposure. Determine whether a page contains material that should be private, obsolete content, or a user-specific interface that does not belong in public search results.
Step 5: Apply appropriate controls. Where a page should not appear in search, consider suitable indexing directives. For confidential information, protect it with server-side authentication and authorization.
Step 6: Verify the outcome. Check the implementation and follow up through the relevant search-engine management tools.
This workflow turns a search query into a controlled review process rather than an invitation to investigate unrelated websites.
Common Misunderstandings About Search Results
A frequent misunderstanding is that ext intitle identifies vulnerable shopping carts.
It does not. The search pattern says nothing definite about a site’s authentication, database configuration, software updates, or payment processing security.
Another misconception is that every .asp address belongs to an abandoned website.
Classic ASP remains usable in supported IIS environments. The extension alone cannot determine whether the application is maintained properly.
A third mistake is assuming that a missing search result proves that a page no longer exists.
Search engines do not provide comprehensive public inventories of every page on the internet. A URL may be excluded from indexing, undiscovered, restricted, or not retrieved for a particular query.
Finally, some users confuse a search query with executable programming code. Search operators filter results; they aren’t instructions executed on a website’s server.
How to Protect Cart Pages From Unnecessary Indexing
When reviewing the results of ext intitle, website owners should distinguish search visibility from actual access.
A noindex directive can instruct search engines not to include a page in their indexes. It does not stop somebody from visiting a publicly accessible address.
Likewise, a robots.txt disallow rule controls crawler access but does not reliably protect confidentiality.
Google also explains that a crawler generally needs access to a page to discover its noindex directive. Blocking crawling can prevent the crawler from seeing that directive.
For pages containing sensitive customer or order information, the appropriate protection is server-side access control.
A responsible website review should therefore consider both indexing and application security.
When information has already appeared in Google, verified website owners can use Search Console’s removal tools to remove results faster while applying a permanent fix.
Don’t mistake a temporary search-result removal for deleting the content or securing the application.
What This Search Can and Cannot Tell You
The most useful way to interpret ext intitle is as a limited discovery tool.
It can suggest that certain publicly indexed resources have ASP-associated filenames and cart-related titles.
It cannot reliably establish:
- Whether a shopping cart is functional or accepting orders.
- Whether the application is running an outdated software version.
- Whether customer information is exposed.
- Whether a payment system is secure.
- Whether the website contains a particular exploitable weakness.
- Whether all relevant pages have been discovered.
Those questions require more reliable evidence than a search results page can provide.
For developers, this distinction prevents unnecessary alarm. For website owners, it encourages practical reviews instead of speculative conclusions.
Conclusion
ext intitle demonstrates how advanced search operators can narrow online research towards a particular type of webpage. The expression combines an ASP filename-extension condition with a title condition associated with shopping carts.
Its most important technical detail is the difference between search engines. Bing documents ext:, while Google’s officially documented file-type operator is filetype:.
The query has legitimate applications in technical SEO, legacy application research, and authorized security assessments. However, a matching search result is only a starting point for investigation.
Responsible interpretation, accurate documentation and appropriate website security controls matter far more than the apparent complexity of the search expression.
FAQs
1. What is ext intitle used for?
It is an advanced search expression intended to locate publicly indexed pages associated with the .asp extension and the word “cart” in their titles. It is relevant to website research, technical SEO, and authorized security investigations.
2. Does ext intitle work on Google?
Google officially documents filetype: rather than ext: for file-type searches. A more appropriate Google expression to investigate is filetype: asp intitle: cart, although results depend on indexing and how Google interprets the query.
3. Is using this search expression illegal?
Search operators are ordinary search features. However, legality depends on the activity, jurisdiction, and circumstances. Accessing restricted information or testing someone else’s application without authorization can create serious legal and ethical problems.
4. Can the query identify vulnerable e-commerce websites?
No. A matching result does not prove any security vulnerability. Search results reveal limited publicly indexed information and cannot replace an authorized technical security assessment.
5. How can website owners prevent cart pages from appearing in search results?
Website owners can use appropriate noindex directives for pages that should remain accessible but not indexed. Sensitive information requires authentication and server-side access controls. Google Search Console can help investigate indexing and request removal of existing results.